Notes on model training
Musings on long-context fine-tuning
Notes on training a 27B vision-language model on long-context examples.
On this page
- Getting one example to train
- Sharing the repeated work
I recently fine-tuned Qwen3.6-27B, an open-weight vision-language model, on a multimodal task that takes an image-text pair and outputs a structured response. Each training example has three parts: a system prompt containing an instruction set (rules, edge cases, and worked examples), the image-text input, which I call the item, and the target output. A complete example is up to about 70K tokens. About 64K of them are the system prompt, and the item and target add at most a few thousand. Each instruction set is shared by a large group of examples, so the same long system prompt appears again and again in the training data. Token counts in this post are rounded, and tensor sizes are calculated from the model’s dimensions for a 70K-token example.
I kept the instructions in the system prompt because they change over time. If the model learned them only through its weights, with no instructions in the prompt, each change would have to be trained in. Continual fine-tuning on the new behavior is the cheaper way to do that, but when the old instructions are baked into the weights, it tends to cause catastrophic forgetting, where the model loses things it had learned before. Doing that well would also need counterfactual examples, the same kind of item with its target under the old instructions and under the new ones, and I had very few. With the instructions in the prompt, the model is trained to follow whatever the prompt says, so a change can start as an edit to the instructions rather than a new training run. I also tried a shorter version of the instructions, but it changed the model’s decisions, so every example kept the full text.
This model handles 70K-token inputs routinely at inference, but training on them takes far more memory, because the backward pass needs intermediate results from every layer of the forward pass. The loss is computed only on the target output, but the target tokens read the instruction tokens, so gradients flow back through all 70K positions. A single example on a single 80 GiB H100 came close to filling it.
The first half of this post is about getting one full-length example through forward, backward, and an optimizer update: the memory budget, Triton autotuning, dropout in one LoRA adapter, collective hangs under FSDP, and a run where the adapters received zero gradients. The second half covers how I computed the system prompt once for examples that share an instruction set, with 75 to 90 of them branching off it inside one buffer. On a standard transformer an attention mask would keep those examples apart, but 48 of Qwen3.6-27B’s 64 layers are recurrent and never look at the mask, so without more work each example would have seen the previous example’s target output.
The earlier workflows, with one example per GPU, took 5 to 7 days each. A two-epoch run with shared instructions, including validation and saving weights, finished in under 20 hours. The two used different data mixes and schedules, so the speedup mixes the effect of sharing with those differences. In practice it moved my experiments from weekly to overnight.
Getting one example to train
Memory per GPU
In BF16 the 27B parameters take about 54 GB, and Fully Sharded Data Parallel (FSDP) splits weights, gradients, and optimizer state across the GPUs, so on 64 GPUs each one stores a shard of under 1 GB and gathers a layer’s full weights only while that layer runs. LoRA shrinks the trainable part further, since the base weights stay frozen and only small adapter matrices get gradients and optimizer state. [1] [2]
Activations grow with the sequence, because almost every tensor passed between operations has one row per token. FSDP does not split activations. Each GPU runs its whole example and holds that example’s activations. I did not split a single example’s sequence across GPUs either. In a capacity test, going from 64 to 128 GPUs halved each weight shard and left the activations exactly as large as before.
For scale, one hidden-state tensor for a 70K-token example has shape [70,000, 5,120], where 5,120 is the model’s hidden width. In BF16 that is about 0.67 GiB. Each layer’s forward pass produces many tensors this size or larger, and backward needs most of them. An early test without activation checkpointing ran out of memory before its first update at about 34K tokens, half the full length.
Activation checkpointing keeps only the input to each decoder layer instead of every intermediate tensor, and recomputes the layer’s internals when backward reaches it. That still leaves one 0.67 GiB tensor for each of the 64 layers, about 43 GiB before anything is recomputed. Recomputing a layer then brings back its feed-forward intermediates, each [70,000, 17,408] or about 2.3 GiB, alongside that layer’s gathered weights and the gradients being accumulated. The 43 GiB is a floor rather than the peak, since temporary buffers and allocator fragmentation add to it, and the out-of-memory errors in the next two sections came from allocations on top of it. [3]
Triton autotuning in the first backward pass
Qwen3.6-27B’s language backbone mixes two kinds of layer. Sixteen of its 64 layers use full attention, where each token compares itself with every earlier token. The other 48 are Gated DeltaNet layers, which carry history forward in a fixed-size recurrent state plus a short causal convolution, more like an RNN than attention. I ran the attention layers on FlashAttention-2, which computes attention block by block without storing the full matrix of attention scores, and the recurrent layers on Flash Linear Attention (FLA) kernels with causal-conv1d. [4] [5] [6]
- Full attention
- FlashAttention-2
- Recurrent path
- FLA +
causal-conv1d
My first full-length backward pass ran out of memory inside Triton’s autotuner for FLA’s normalization-backward kernel, l2norm_bwd_kernel. FLA 0.5.2 had no pre-tuned configuration for this kernel on H100 in my setup, so on first use Triton benchmarked candidate tile sizes and launch settings to pick the fastest. Benchmarking needs its own workspace, and with the backward tensors already filling the GPU, that workspace was the allocation that failed. [7]
The tuning key for this kernel is the feature width plus a size bucket that grows with the number of rows, NB = cdiv(T, 65536), so a full-length run falls in a bucket that a short run never tunes. I ran a one-update job on every node with the instructions cut to about 10,000 characters, let Triton finish its search with plenty of free memory, and took the winning tile. I wrote that tile as the default_config in FLA’s cache file for the kernel, with no shape-keyed entries, and launched with FLA_CACHE_MODE=default. In that mode FLA returns the default configuration without looking up the key, so full-length backward used the pinned tile and never started a search. A pre-launch check on every node confirmed the cache mode and the loaded configuration before step 0.
LoRA dropout on down_proj
I kept the vision encoder frozen and trained LoRA adapters in the language model, along with the vision-to-language projector, which Qwen calls the merger. The merger maps the vision encoder’s features into the representation the language model reads, so training it changes how the model uses images without unfreezing the encoder.
The next out-of-memory error came from one of the language-model adapters. In each layer’s SwiGLU feed-forward block, gate_proj and up_proj expand the hidden width from 5,120 to 17,408, and down_proj maps it back to 5,120. A LoRA adapter on down_proj therefore takes the 17,408-wide intermediate as its input. [8]
The adapter has rank 8, but the reduction to rank 8 happens after dropout. LoRA applies dropout to the adapter’s input, which creates a new tensor the same size as that input along with a mask of the same shape. LoRA A is trainable, so its weight gradient needs the exact input it saw, and the dropped-out copy stays in memory until backward reaches it. For down_proj at 70K tokens, that is a [70,000, 17,408] BF16 tensor of about 2.3 GiB plus a 1.1 GiB mask, 3.4 GiB in each layer while it is recomputed. The frozen base projection adds nothing, because its weight needs no gradient and its backward uses only the incoming gradient and the weight.
down_proj adapterSchematicI removed the adapter from down_proj, which removed both tensors. Setting dropout to zero would have removed the mask and the separate copy, but LoRA A would still keep its 17,408-wide input, about 2.3 GiB, for its weight gradient. For the runs with one example per GPU, I used rank-8 adapters with dropout 0.05 on q_proj, k_proj, v_proj, o_proj, and gate_proj, and none on up_proj or down_proj.
Collective hangs under FSDP
Some runs stopped advancing with no out-of-memory error and no traceback. Under FSDP, each GPU process, called a rank, stores only a shard of each layer’s weights. Before a layer runs, all ranks join an all_gather to assemble its full weights, and they free them afterwards. With activation checkpointing, backward recomputes each layer, so the gathers happen again during backward. An NCCL collective such as all_gather finishes only when every rank in the group makes the same call in the same order. If one rank takes a different path, the others wait inside the collective for a call that never comes, and that is where these runs were stuck. [2] [9]
During these hangs, nvidia-smi showed 100% GPU utilization, because the NCCL kernel spins while it waits, but board power sat around 120 W instead of the 600–700 W of real computation. Utilization and power together were the quickest sign of a hang. To find the call each rank was stuck in, native stack dumps from py-spy on every rank told me more than the logs did.
In one hang, the requirements files matched on every node, but one worker had imported a different minor version of Transformers, which issued different collectives in backward. I added a pre-launch check of the versions each node actually imports, rather than the versions the requirements file lists.
When I tried DeepSpeed ZeRO-3, it stalled inside parameter gathers during backward recomputation, and Hugging Face Trainer’s gradient checkpointing stalled the same way under FSDP. What worked was FSDP’s own activation checkpointing through Accelerate (fsdp_activation_checkpointing: true), with Trainer’s --gradient_checkpointing flag turned off, so that recomputation and its gathers followed a single path controlled by FSDP. [10]
Any step that only some ranks take causes the same kind of hang. If one rank meets an over-length example and skips it, the others will wait for it at the next gather. Every rank therefore shared a skip flag through an all_reduce, so either all ranks skipped the batch or none did. Assembling a full state dict for a save also uses gathers, so every rank has to take part even though only rank 0 writes the file.
Sanity check for training
Zero adapter gradients
After the switch to FSDP’s checkpointing, training ran, the loss values looked plausible, and grad_norm was exactly 0.0 on every step. The input embeddings are frozen, so their output does not require gradients, and the first decoder layer received an input with requires_grad=False. Calling model.enable_input_require_grads() before accelerator.prepare(model) marks the embedding output as requiring gradients without unfreezing the embedding weights, and the adapter gradients came back.
Precision during recomputation
Recomputation has to produce tensors with the same dtypes as the ones saved in forward. I had loaded the weights in BF16 and also enabled Accelerate’s BF16 autocast. With both in place, some tensors saved in forward and their recomputed versions disagreed, one BF16 and the other FP32, and backward raised CheckpointError. Setting mixed_precision: no removed the autocast layer while the weights stayed in BF16, and forward and recomputation then produced matching dtypes.
Memory across updates and saves
With those fixes, I ran two full-length optimizer updates in a row. Adam creates its moment tensors for the trainable parameters during the first update, so only the second backward pass runs with them already in memory; a one-update smoke test never sees that peak. I also saved the weights, since gathering a full state dict has its own memory pattern. I tracked peak allocated and reserved GPU memory through both updates and the save, and all three fit. [2] [11]
At that point one complete example per GPU trained correctly. I’ll call this setup, with each example in its own sequence, standalone training. Every example still brought its own copy of the instructions through forward and backward.
Sharing the repeated work
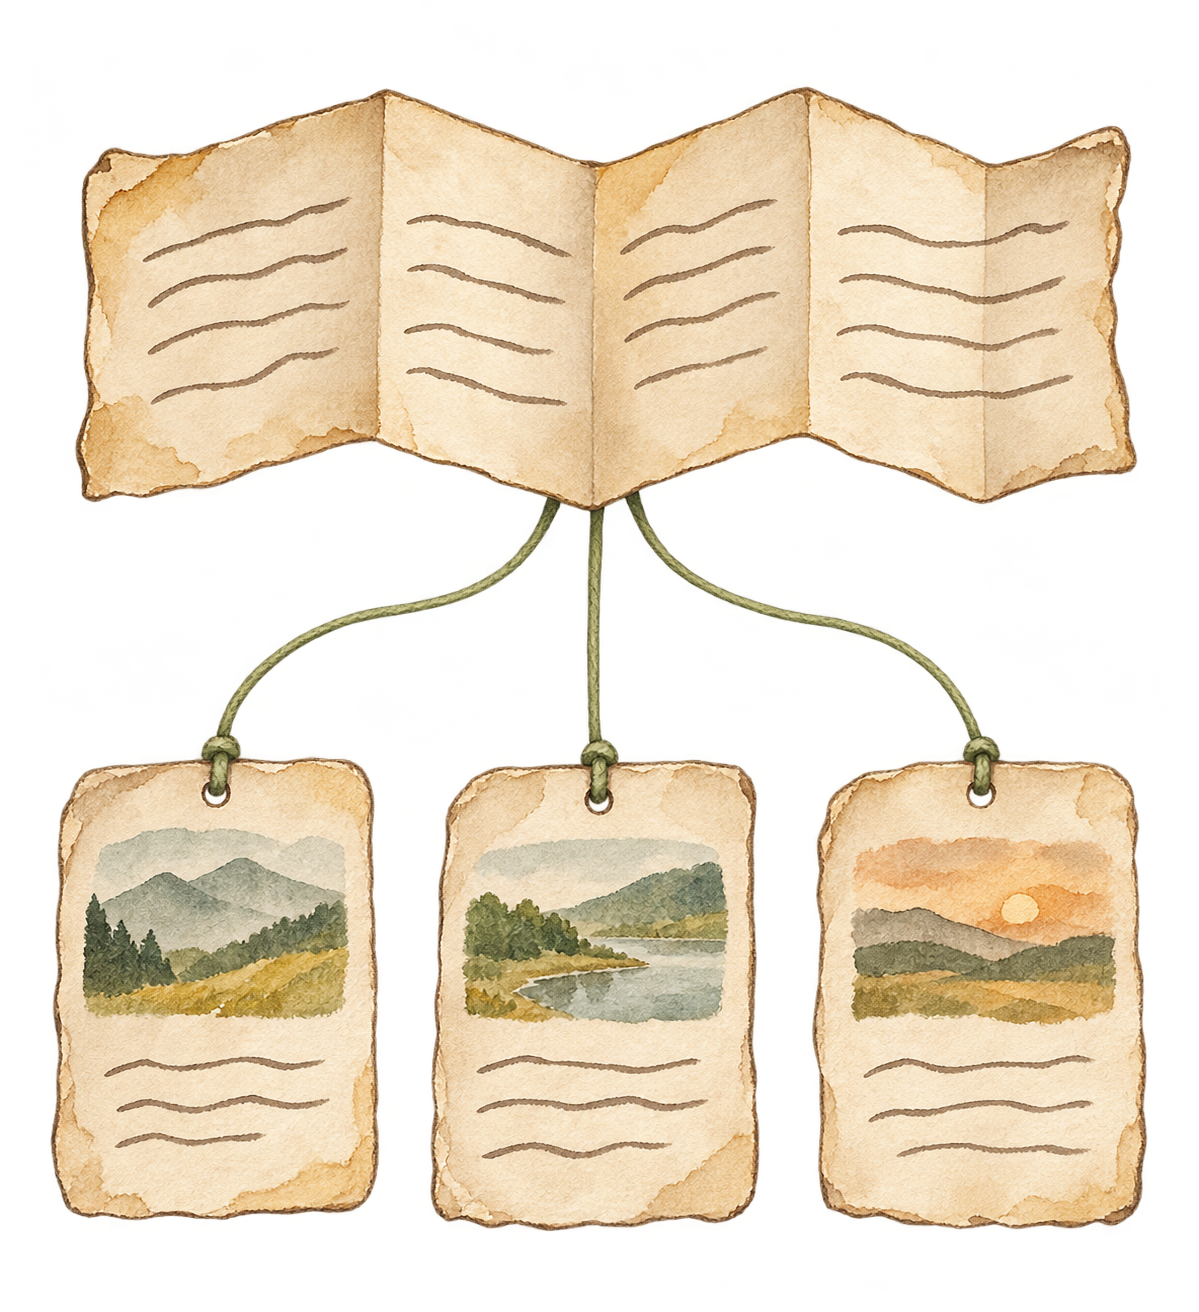
Computing the system prompt once
Standalone training processes every example on its own, so a system prompt shared by thousands of examples goes through forward and backward thousands of times. Most of that work is identical across examples, because the system prompt comes first and, in a causal model, a token can only read the tokens before it. The system prompt’s representations therefore do not depend on which item follows. Given the same tokens, positions, weights, and random choices, they come out the same for every item. They can be computed once, with several items branching off them. From here on I call the system prompt P, and the part of an example that follows it, the item together with its target output, a continuation.
Ordinary sequence packing puts several examples into one buffer to avoid padding, and each example keeps its own copy of the system prompt. [12] In my packs, each buffer held P once, followed by 75 to 90 continuations, all from examples that used the same instruction set. Physically the continuations sit one after another. Logically each one can read only P and its own earlier tokens, as if it were the only continuation.
Inference servers do something similar with prefix caching, where requests that start with the same tokens reuse the stored state for those tokens. [13] Training differs from that because gradients have to flow back through P, and every optimizer update changes the weights that produced P’s representations. So P is shared only within one pack, during its forward pass and the recomputation in backward, and computed afresh for the next pack.
Continuation = item + target; widths schematic
Repeated work in standalone training
For a causal full-attention layer, the first token of P can attend to itself, the next to two tokens, and so on. If P has tokens, it has attention pairs. A continuation of tokens, including its item and target output, adds pairs reading P, plus within the continuation. [4]
For equal-length continuations, standalone processing repeats P’s pairs times. Sharing computes those once. Each continuation still pays its own work reading P and its own within-continuation work.
For illustration, take a 64K-token system prompt and 80 continuations of 1K tokens each, counting both item and target output. Each standalone example is then 65K tokens long. Processing all 80 separately materializes 5.2 million token positions across their separate buffers. Sharing P needs one 144K-position buffer, about 36 times fewer positions, while each continuation still sees a 65K-token logical sequence.
Visible full-attention pairs fall from about 169 billion to 7.2 billion per layer and attention head, about 23 times fewer. That ratio is smaller than the drop in positions because every continuation still attends to all of P.
For a pack to train the same way as standalone examples, each continuation has to see exactly what it would see on its own: the same P, at the same positions, and nothing from the other continuations. On the way back, each continuation’s gradient has to reach P. The next three sections take these in turn: positions in the attention layers, isolation in the recurrent layers, and the backward pass.
Keeping standalone positions
Take a text-only version of the illustration. P occupies positions 0 through 63,999. In standalone execution P → B, continuation B starts at position 64,000, right after P’s last token. Store P → A → B instead, with continuation A taking 1,000 tokens, and B’s physical start moves to 65,000. Using that buffer index as its position ID would place B’s first token 1,001 positions after the end of P. A mask can hide A’s tokens, but it cannot undo this change in B’s distance from P.
In the full-attention layers, a token’s query vector is compared with other tokens’ key vectors to decide what information to read. Position encodings make those comparisons sensitive to where the tokens occur. Rotary Position Embedding (RoPE) rotates pairs of query and key components by angles determined by position, with different pairs rotating at different frequencies. The relative rotation in their dot product depends on the difference between their position IDs. Changing B’s position relative to P therefore changes attention scores even when the visible tokens are unchanged. [15]
So I gave B the position IDs it would have in P → B, starting at 64,000, without moving it in the buffer. A also starts at position 64,000. Two continuations with the same position numbers would be a problem if they could see each other, so I used a block-sparse FlexAttention mask that lets each continuation read P and its own earlier tokens and hides every other continuation. In packed training, this FlexAttention path replaced FlashAttention-2 in the 16 language attention layers. Transformers had FlexAttention switched off for this model class (_supports_flex_attn = False), so I enabled it for those layers only and left the vision encoder on its own attention backend.
For the actual image-text inputs, the model used Multimodal RoPE (M-RoPE): temporal, height, and width coordinates control different query/key components. Text uses the same position along all three axes; image tokens also carry row and column coordinates. Tokens across one image row, for example, can share a height coordinate while their width coordinates change. The Qwen team’s M-RoPE introduction shows how these coordinates represent text, images, and video. [16]
For a 2D image, the positional cursor advances by , where H and W are the visual token grid’s height and width after spatial merging. Take a 14 × 20 grid as seen by the language model. It occupies 280 physical token slots, but its height and width coordinates advance in parallel: rows span 14 positions and columns 20. If the grid starts at coordinate , its largest coordinate is , so the cursor following the visual block is . Advancing by 280 instead would put subsequent text 260 positions too far ahead. Surrounding text and image boundary markers get their usual text positions. [17]
For each packed continuation, I generated its 3D coordinates with a local origin at zero, then added the length of P, which is text only, to all three axes. The shifted coordinates match those the continuation has in its standalone example, with P’s length applied once. The image keeps its spatial layout, and every continuation starts at the same position after P. The causal mask still uses physical token order within each continuation, because height and width coordinates describe the image’s layout, and comparing them as if they were buffer indices would give the wrong causal order.
The vision encoder needed no change, because all the images in a pack go through the frozen encoder as one batch and cu_seqlens keeps each image separate, with its own 2D rotary positions starting from zero. The merger then places each image’s tokens into that continuation’s slot in the packed buffer.
Isolating the recurrent layers
Positions and the mask take care of the 16 attention layers. The other 48, the Gated DeltaNet layers, never look at the mask. They carry information forward token by token through a recurrent state and a short convolution buffer, across the whole buffer. During training, a continuation contains its target output as well as its item. If B started from the state A left behind, that state would include A’s target output, so B would be trained while seeing the answer to a different example, something it never sees on its own or at inference.
For one head, write the running memory matrix as . The gated delta update first decays that memory, then corrects what it predicts for the current key:
Here and are the current token’s key and value vectors. The input-dependent factor , with , controls decay; controls the strength of the correction. The term reads the value predicted by the decayed memory, and the update writes the difference from back along the key. The current token’s query reads the updated matrix to produce that head’s recurrent-attention output. After the last token of P, this matrix is , the state each continuation must start from. [18]
I patched both routes by which that history crossed a continuation boundary. A width-4 causal convolution reads the current input and three preceding inputs. To give each continuation the right local history, I placed P’s final three convolution inputs in front of each continuation, used seq_idx to keep the segments from reading each other, and dropped the three warm-up outputs afterwards. For the recurrent update, chunk_gated_delta_rule processed P once to produce . Every continuation received that same state through initial_state, with continuation boundaries given by cu_seqlens. [14]
Backward through P
P’s final state is also a shared node with one branch per continuation. Let the two target-output losses be LA and LB, and let their sum be L. Each loss contributes a derivative with respect to . The chain rule adds those contributions at the shared state:
The combined gradient then flows back through the computation of P. If the loss is an average rather than a sum, each branch’s term is scaled by its averaging weight; with the same averaging in packed and standalone training, P receives the same total gradient.
The convolution tail is a second gradient route into P. Every continuation reads the same final three convolution inputs, so the gradients through those inputs also sum into P. My backward pass accumulated both the initial-state gradients (dh0) and the convolution-tail gradients. The same rule, summing at a shared node, applies to P’s keys and values in the attention layers. Recomputation in backward has to rebuild the same branches and state routes, so the pack layout stays active during recomputation too.
All of this also assumes the same random choices. With dropout on, P is computed once per pack, so every continuation in the pack sees the same dropout mask on P, while standalone examples would each draw their own. On average the gradient is the same, but a single update is not, which is why the small-model check below ran with dropout off.
Checking the packed computation
On a small hybrid model in float64 with dropout off, packed and standalone runs gave the same forward outputs and the same summed gradients for the LoRA adapters and the merger. On the real 27B model in BF16, I ran the same 64 examples standalone and packed and compared their losses. The mean losses were 0.4063 and 0.4064. Per example, the mean absolute difference was 0.007, and the largest difference was below 0.04.
Fitting a pack in memory
A pack holds P plus all of its continuations, so it is longer than any standalone example. An epoch processes far fewer positions in total, but each buffer has a higher peak.
The largest single tensor would have been the logits. The language-model head turns each hidden state into a score for every vocabulary entry, and Qwen3.6-27B has 248,320 of them. For the 144K-position buffer in the illustration, BF16 logits at every position would take about 71.5 GB, or 66.6 GiB, most of an 80 GiB GPU on their own. [8]
Only target-output tokens have a loss, so only their logits are needed. In a causal model the hidden state at position predicts the token at position , so I gathered the hidden states just before each target token (answer_pos - 1) and ran lm_head on those alone. Gradients still flow back through P and the items, because the target tokens read them through attention and the recurrent state.
Checkpointing still keeps each decoder layer’s input, about 43 GiB across 64 layers at 70K tokens, and more for a pack, which is longer. I offloaded those layer inputs to pinned host memory during forward and streamed each one back when backward reached its layer, while the intermediates recomputed inside a layer stayed on the GPU. The offload worked in fixed 64 MiB chunks. PyTorch’s pinned host allocator rounds each allocation up to a power of two and caches it, so a layer input just over 1 GiB took a 2 GiB block, and with packs on both sides of that boundary, a node kept both pools and ran out of host memory. Uniform chunks kept pinned memory close to the actual tensor sizes. I also capped pack size, with a best-fit planner filling packs from examples with the same system prompt up to a token budget.
With target-only logits, checkpointing, offloading, and bounded packs, peak memory stayed between about 55 and 65 GiB on the 80 GiB H100s. Over a full epoch, with real continuation lengths and pack sizes, sharing P cut the total number of token positions processed by about 45 times.
Packing led to changes in gradient steps
With one example per GPU on 64 GPUs, each optimizer update saw 64 examples. With around 75 continuations per pack, it saw more than 4,000, and an epoch took a little over 200 updates instead of about 15,000.
Within each pack, I averaged the token cross-entropy over each target output first and then averaged across the examples, so a long target output did not count for more than a short one just because it had more tokens.
With so few updates, the learning-rate schedule needed another look. Cosine decay had worked well in the standalone runs. In packed runs, a constant 2e-4 after a ten-step warmup did better on held-out validation, raising the downstream task’s success metric by 0.5 to 1.8 percentage points, and a second epoch improved it further. My reading is that with only about 400 updates over two epochs, decaying the rate cut learning short.
A single overnight packed run, starting from the off-the-shelf base model, scored about 1 percentage point higher on the same metric than my earlier model, which had been built over weeks of several standalone training stages.
The shorter runs let me test learning-rate schedules and adapter placements and look at the errors the next day.
References
- LoRA ↗
- PyTorch FSDP ↗
- PyTorch activation checkpointing ↗
- FlashAttention ↗
- FLA ↗
- causal-conv1d ↗
- Triton autotuning ↗
- Qwen3.6-27B model configuration ↗
- NCCL collective operations ↗
- Accelerate: FSDP activation checkpointing ↗
- PyTorch CUDA memory management ↗
- Efficient Sequence Packing without Cross-contamination ↗
- vLLM prefix caching ↗
- Tree Training ↗
- RoFormer: rotary position embeddings ↗
- Qwen: multimodal rotary position embeddings ↗
- Transformers: Qwen multimodal position IDs ↗
- Gated Delta Networks: the gated delta rule ↗